


Inside This Issue
Welcome to AI-Ready Data Access Insights. This issue is full of stories about teams getting their data where it needs to go, faster and more simply than they expected. Here’s what’s inside:
- A Fortune 500 retailer, its outsourcer, and its systems integrator all chose PropelZ. Each tested it against their own requirements, and all three said yes. Our new customer white paper shares what they found.
- For ISVs receiving customer data, and for teams sharing data with business partners. Two new blog posts cover both sides. One shows ISVs how to bring customers live in days. The other shows teams how to feed every business partner without writing another extract.
- How to give cloud apps live access to mainframe VSAM data without moving it. Our latest webinar shows how Lozen lets cloud applications read and update mainframe data right where it lives, with one copy, no pipelines, and your existing security in place.
- Move a million data sets with a single job. Give the PropelZ Multiplexer your list of files, and it schedules, runs, and tracks every transfer for you. It speeds up when your system has room and eases back during business hours. Hear how on the latest Skyward Data episode.
- Explore at your own pace. The Customer Briefing Center is open whenever you are, with no sales pitch.
We hope you find something here you can put to work. ↓
Customer White Paper
Faster mainframe data movement, proven at enterprise scale
See what three organizations tested, and why all three chose PropelZ.
Three Companies. One Choice.
A Fortune 500 retailer, its outsourcer, and its systems integrator had access to plenty of established data movement tools. When they needed large volumes of mainframe data in Google Cloud on a firm deadline, none of those tools could move it fast enough. Some of the datasets held more than 200 million records.
“We already owned most of the legacy mainframe data movement tools. None of them could move data to Google Cloud at the scale, and with the simplicity, this program requires. PropelZ did.”
— Senior Director of Engineering, Fortune 500 Retailer
So they tried PropelZ. Each team tested it against what mattered to them: data integrity, security, cloud delivery, and fit with how they already run their mainframe operations. Transfers they had expected to take 12 to 14 hours finished in 2 to 4, and every one was checked for accuracy and completeness.
All three said yes. The white paper walks through what they tested and what they found.
New on the Blog
In this issue, we’re featuring two new blog posts written from the two sides of the same data exchange.
- The first is for ISVs whose platforms depend on data from their customers.
- The second is for the teams inside those customers who have to deliver that data to every business partner they work with.
Each post shows how PropelZ gets the data flowing faster for everyone involved. Zafin and one of its bank customers show both sides in action.
For ISVs Receiving Data From Their Customers
Your Customers Send What They Have. Your Platform Takes It From There.
For ISVs, this changes how customer onboarding works. With PropelZ built into your platform, every new customer can go live in days. They send the data they already produce, in the format they already use, and they install nothing.
PropelZ runs wherever your platform runs and reads whatever your customers send: copybook-described mainframe files, VSAM exports, database tables, delimited files. You map each customer’s layout once. There’s no parser to write, no one-off intake to maintain, and a changed layout means a quick mapping edit, not a code project. Every customer comes on through the same engine, so the hundredth is as easy to bring live as the tenth.
That also opens the door to customers whose IT teams never had time to build you an extract.
Zafin built PropelZ into its banking platform to decode mainframe data from its bank customers directly. As Shahir Daya, Zafin’s Chief Product and Technology Officer, puts it:
“We’ve increased throughput, reduced unnecessary processing layers, and improved operational efficiency.”
For Teams Sharing Data With Business Partners
Your Partners Get What They Need. Your Team Never Writes Another Extract.
If your business shares data with service providers and ISV platforms for pricing, billing, payroll, loyalty, fraud, or incentives, PropelZ gives your team one way to feed them all. Each new partner goes live in days, and every platform you’ve invested in starts delivering sooner.
PropelZ reads your data where it sits, on z/OS, IBM i, Linux, Windows, or in the cloud. It sends each partner only the fields they need, straight to wherever they already look. The COBOL copybook you already maintain is the layout, so adding a partner means a mapping and a schedule, not a new program. When a partner’s spec changes, you edit the mapping.
Your partners don’t have to change anything on their side. Your existing extracts can retire one at a time, at whatever pace suits your team. On z/OS, the processing runs on zIIP engines, so you can share more often without adding to your software bill.
One top-tier global bank decided it didn’t want to keep building extracts for Zafin, its pricing and billing platform provider. The bank asked Zafin to implement PropelZ, and Zafin built it into its platform to take what the bank already sends, as-is.
Press Play
Now Streaming on the VirtualZ YouTube Channel
One channel. Every angle. Start here.
Our curated playlists walk you through AI & Modernization Strategy, Use Cases in Action, Product Deep Dives, Security & Compliance, Strategic Partner Conversations, and more — in the order we recommend watching.
How to Give Cloud Apps Live Access to Mainframe.
VSAM Data Without Moving It.
Your Mainframe Data, Live, Wherever You Need It.
What if your cloud applications could work with mainframe data right where it lives? In our recent webinar, our co-founder and CTO Vince Re walked through how Lozen makes that possible.
With Lozen, applications running in the cloud or on distributed systems can read and update VSAM files, sequential datasets, and other mainframe data in real time, as if the data were local. There’s one copy of the data, so there’s nothing to sync, and every read returns the current record. Your existing mainframe security rules keep doing their job. The work is zIIP-eligible, and there’s no code or pipeline to build and maintain. Only the records an application actually uses travel over the network.
In Vince’s words:
“It’s not just access to the data, it’s full integrity of the data, whether you’re reading it or writing it.”
Vince also covered when replication is the better fit, such as database-style access or heavy AI and analytics workloads, and how PropelZ handles that with the same no-code, zIIP-eligible approach. As he put it, “Sometimes it’s Lozen, sometimes it’s our replication strategy, sometimes it’s both.”
On the Skyward Data Podcast
A Million Data Sets, One Job
On the latest episode of Skyward Data, Executive Chairman Marc Sokol and CTO Vince Re talk about the PropelZ Multiplexer. It lets your team hand over a list of 100,000 or even a million data sets and have a single job handle the rest.
You give the Multiplexer your inventory and a limit on how many transfers can run at once. From there, it schedules every PropelZ transfer, checks resource use minute by minute, and raises or lowers the number running in parallel to match what your system, network, and target can take. It can open up overnight and ease back during business hours. The status of every file goes to a simple log and the operator console, so the automation tools you already use can keep watch.
Marc and Vince share what one team saw: 9,000 disk, tape, and GDG data sets that used to run from Friday night to Monday morning finished in a couple of hours. They also walk through splitting one multi-terabyte table into a hundred parallel operations. And they cover where teams are putting this to work, from daily partner data feeds and log files across dozens of LPARs to feeding Databricks and Snowflake for AI and analytics.


Skyward Data is THE podcast for professionals who want to gain a competitive edge in the evolving data landscape. Join us on your favorite platform, and subscribe to remain ahead of the competition.
Any Platform. Any Input. Any Output. One Patented Portfolio.
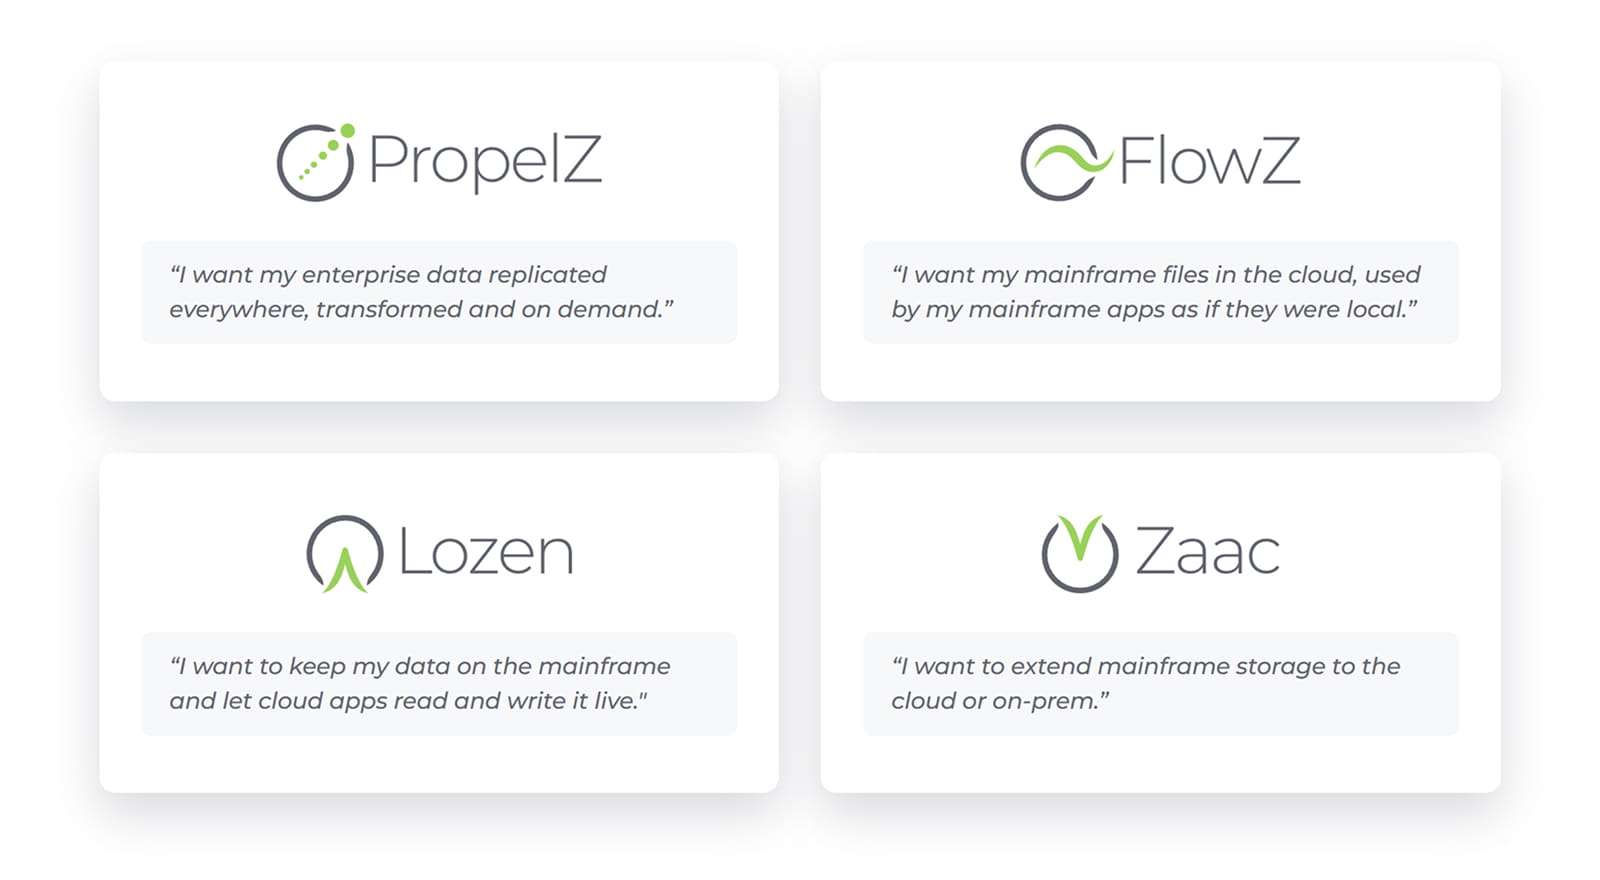
On-Demand Customer Briefings
Today’s enterprise leaders want insight, not a sales pitch. That’s why we created the VirtualZ Customer Briefing Center — a self-paced, no-pressure environment where you can explore our patented, no-code data access software when and how it works for you.

“These briefings are designed to put customers in control. They make it easy to explore how our solutions solve real-world problems — at your own pace, with clarity and no noise.”
— Vince Re, CTO, VirtualZ Computing
Thank you!
Thanks for spending a few minutes with us this month.
Whether you’re modernizing storage, accelerating AI, or powering compliance, VirtualZ is here to help you unlock mainframe data with less friction — with our no-code solutions, you can start delivering results today.
Ready when you are:
- Explore at your own pace in the Customer Briefing Center
- Watch demos and webinars anytime on YouTube
- Reach out directly at hello@virtualzcomputing.com
See you next month with more ways to modernize, integrate, and accelerate.
— The VirtualZ Team